Scalable meta-learning from hindsight
Technical reportResearch and component study
PDF: Technical report · presentation revision 24 October 2026.
Code: Curated implementation, tests and retained evidence; large model weights and tensor artifacts are not bundled.
An agent finishes a task knowing more than it knew while acting. It has seen the failed test, the consequence of a mistaken assumption, the correction that finally worked, or the outcome of its chosen strategy. A useful learning system should turn that experience into better behavior on the next task—not merely produce a persuasive explanation of the last one.
This project asks whether we can learn the teaching procedure itself. The objective is not to make a model better at writing reflections. It is to make a teacher better at causing learning, then compress that teaching procedure into a direct mapping from completed experience to policy targets.
I designed and implemented two connected learning systems around that question. The outer system proposes source-derived lessons and measures the improvement their updates cause in matched students; its measured reward can train the proposer. The inner system learns to assign the selected full-vocabulary distributions directly from raw completed experience, then distills them into a causal student. The component study separates three achievements that can otherwise look deceptively similar: useful information in context, accurate imitation of a teaching distribution, and improvement retained in the student’s parameters.
Judge teaching by the learning it causes
Suppose a model gets an array-transformation problem wrong. A strong assistant can inspect the completed attempt and say, “Keep only the longest nonzero run; remove the isolated entries.” That may be an excellent instruction for solving another array. It does not follow that training on the original attempt under that instruction will teach the student to apply the rule independently.
The learning objective must reflect that difference. A candidate lesson is valuable if the update it induces improves performance on different tasks after the lesson has been removed.
The slow outer procedure makes this measurable:
- A proposer reads one completed source experience: the task, the model’s original response, and observed feedback. It proposes privileged-information contexts, or PI. It does not receive the validation or query tasks it will be judged on.
- Each PI conditions a snapshot of the model. That snapshot supplies a probability distribution over the vocabulary at every original response position.
- Matched student clones start from the same parameters and fresh optimizer state. Each receives a bounded distillation update from one candidate’s distributions.
- The updated students answer related validation tasks causally, without the PI. Their improvement determines the candidate’s learning value. No update is a legitimate alternative, preferred on ties.
For a candidate , the relevant reward is
Here is the candidate teaching distribution, is the prescribed -step student update, and measures validation performance. The candidate is not rewarded for explaining the source elegantly, matching its answer, or helping while remaining in the next task’s prompt. Those may be useful diagnostics, but the target is learning that survives the intervention.
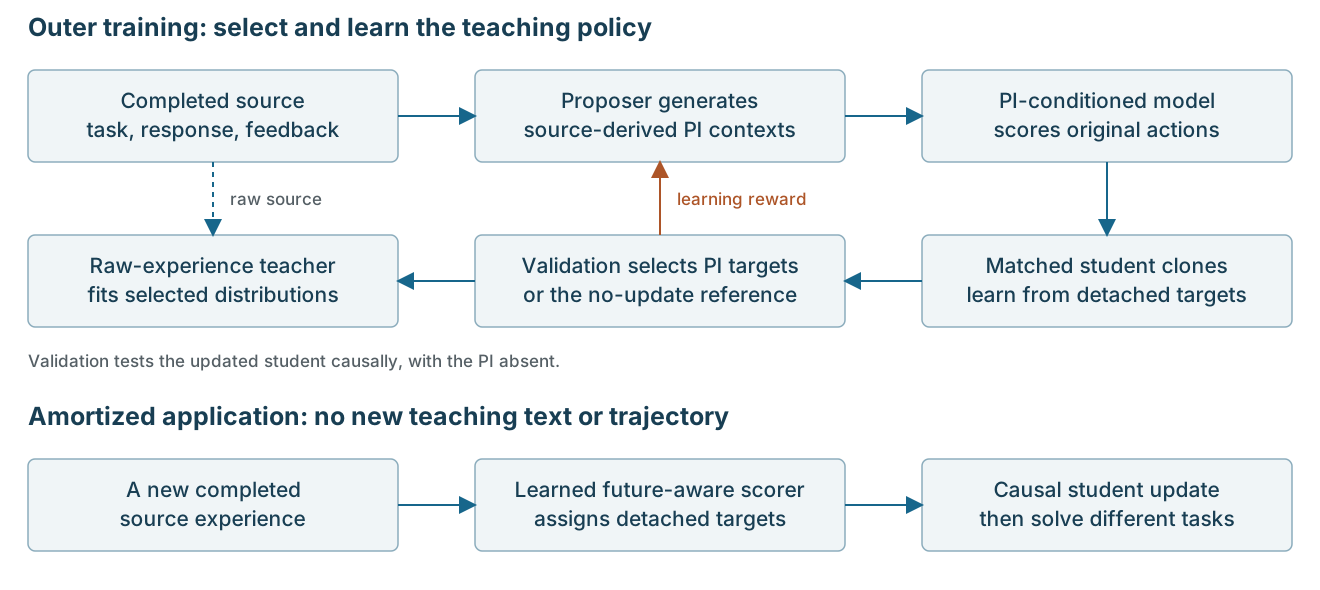
This is a meta-learning objective: improve the process that produces a learner’s update. The proposer can be optimized by policy-gradient or preference methods, treating the update and evaluation as a black box. There is no need to differentiate through the entire student-training computation. There is still a real outer-loop bill: proposing candidates, scoring targets, cloning updates, and measuring their consequences.
One cheaper outer-loop option scores a source-derived lesson directly on related tasks, skipping the cloned updates. This contextual reward could rank candidates or train the proposer, but its agreement with actual update value needs paired validation; the completed proposer run below used actual-update rewards.
Learn the policy assignment rather than the lesson text
Repeating that search after every ordinary experience would be expensive. Its second purpose is to generate targets for a hindsight teacher.
The winning lesson defines a distribution over the actions in the original rollout. A future-aware teacher learns to predict that distribution from the raw completed experience alone. It does not need to reconstruct the hidden lesson, write a reflection, sample a corrected answer, or generate another environment trajectory. Its output is already in the form the student can learn from: a distribution over possible next tokens.
For source response tokens , the student minimizes the full-vocabulary forward KL
The stop-gradient operator detaches the teacher targets. In the reference construction, comes from the PI-conditioned causal model. In the amortized construction, the learned hindsight model supplies it directly from the completed source.
Once that teacher is useful, the scale argument is amortization: candidate search, cloned updates and repeated validation belong to outer training; ordinary learning becomes scoring the experience, detaching the distributions and updating the causal policy. Generating new teaching text is not part of that path. The original rollout, full-vocabulary scoring and student backward pass still cost compute; “no extra sampling” does not mean “free learning.”
The teacher is allowed to see the historical token it scores, along with later tokens and feedback. That is deliberate. Its label is not the visible token; it is a selected policy distribution that may assign the token very low probability. Seeing a bad action does not make copying that action the objective. Whether the fitted teacher uses this information productively is an empirical question.
Future visibility also does not make every retrospective correction transferable. The causal student can learn to check a schema before editing it, but cannot know in advance an unpredictable error message from a later tool call. It must improve under the information available when acting, not merely judge better after the outcome is known.
Engineering the learning intervention
The implementation is built around the details that determine whether this experiment means what it appears to mean.
The same actions must be scored. Adding PI changes the prompt’s length, but must not retokenize or replace the student’s original response. Teacher and student logits are aligned to the same original token IDs, using the predecessor position for each next-token prediction. A change in that alignment can manufacture an apparent learning effect.
Every intervention must start from the same learner. The system resets student adapters and optimizer state between candidate updates. Targets are detached, evaluation is causal, and the PI is absent from the adapted student’s validation and query prompts. Query results do not select lessons or update settings within a comparison.
Future access and shared weights are different choices. A more self-contained endpoint would use the actor’s own parameters for both causal action and hindsight scoring. The completed fitted-teacher comparison examines the components before coupling those roles: it uses separate rank-16 teacher and student LoRA adapters on a common frozen Qwen3.5-4B base. The teacher’s eight full-attention layers can look across the completed sequence; the twenty-four DeltaNet operators remain causal, although they can consume already future-informed representations. This is a future-aware hybrid, not a model in which every layer has become bidirectional. A common base is also not a demonstration of a shared-weight learning loop.
A no-update decision must mean what it says. The reference selector can choose a neutral causal distribution. An amortized teacher only approximates that distribution, however, and a small residual can still generate a nonzero parameter update. A reliable learning system needs to distinguish “approximately preserve the policy” from a literal no-op.
The code also implements candidate filtering, exact-match task grading, matched controls, result identities, work counters and independent numerical checks. These interfaces make each intervention inspectable from original actions through target distributions and parameter changes to the resulting student’s answers.
Three different questions in the empirical study
The development study uses four families of short array transformations: translation, denoising, size-based recoloring and gravity. Each learning episode has one completed source task and separate validation and query tasks from the same family. The student must solve new inputs, not repeat the source answer.
This is a controlled setting for studying the update mechanism. It is not yet a demonstration on long-horizon coding agents or unseen task families. The main fitted-teacher comparison contains eight independently adapted sources, with eight queries per source. These are development cases, repeatedly inspected during research; the sixty-four queries are not sixty-four independent learning experiments.
Useful context does not automatically become useful parameters
On an earlier balanced set, source-only distillation raised query accuracy from 23/64 to 36/64 with the lesson absent at evaluation. That is positive component evidence that this interface can transfer information into parameters.
On the fresh sources used for the fitted-teacher study, the picture was different:
| Condition on the same tasks | Validation correct | Queries correct |
|---|---|---|
| Unchanged student | 24/64 | 27/64 |
| Source-derived lesson in context | 40/64 | 42/64 |
| Four source updates, lesson absent | 44/64 | 30/64 |
The lesson still contained useful information: direct PI solved twelve query tasks the adapted student missed, with no task showing the reverse. But much less of that benefit survived this parameter-update recipe. A good contextual teacher and a good training intervention are not interchangeable.
A hindsight teacher can learn the distribution assignment
The future-aware teacher was fitted on eight earlier source experiences, using PI or neutral references selected by their actual validation-update results. These targets used fixed externally proposed lessons; the learned proposer discussed below was a separate, later component study. On eight fresh experiences, mean forward KL to the selected reference fell from 0.2791 to 0.0583, improving on every source. No extracted lesson was provided to the fitted teacher.
This shows generalization of the distribution-matching component. The corresponding downstream scores were 30/64 for students taught by the fitted teacher, 27/64 without an update, 28/64 with the unfitted future-aware teacher, and 30/64 with explicit PI targets. The source-cluster uncertainty intervals for the fitted teacher’s gains include zero. Equal totals with explicit PI also conceal seven wins and seven losses between the two students; they do not establish equivalence.
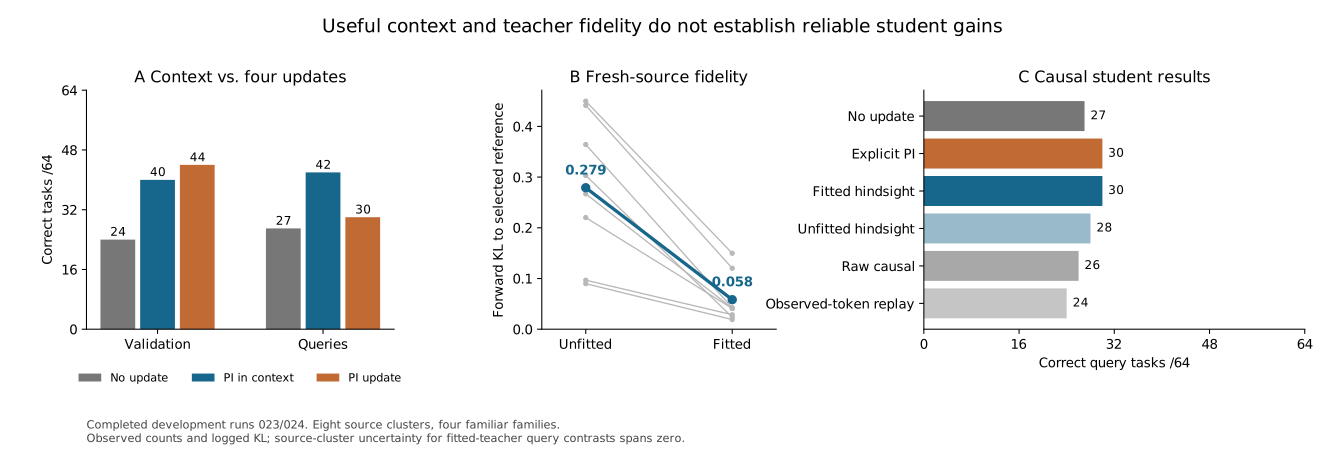
The result is not “the teacher failed to fit.” It learned a substantial part of the policy assignment. The unresolved question is whether the learned targets reliably cause useful learning on new tasks.
Low imitation loss can miss the decisions that matter
To examine that gap, I reconstructed all eight explicit-PI student updates and audited the full distributions before and after training. This analysis reused saved experience and generated no new answers.
Average source KL fell from 0.2466 to 0.0233. That initially looks like strong imitation. But 98.54% of the initial KL, summed across the source positions, was in the verbal rule sentence. At all 150 array-value positions, teacher and initial student had the same most likely next token; so did the updated student. At the first wrong array entry in all four incorrect source responses, the PI teacher still preferred a wrong value.
That does not mean the distributions were identical, or that a non-argmax shift cannot matter. It identifies where the measured discrepancy was located. In one translation example, the teacher increased the correct value’s probability from 0.46% to 8.50%, while the updated student reached only 0.86%, despite a 92.4% reduction in average source KL. In the recoloring examples, the local fitting pattern went the other way and overshot the target. Aggregate loss concealed uneven fitting at task-relevant positions.
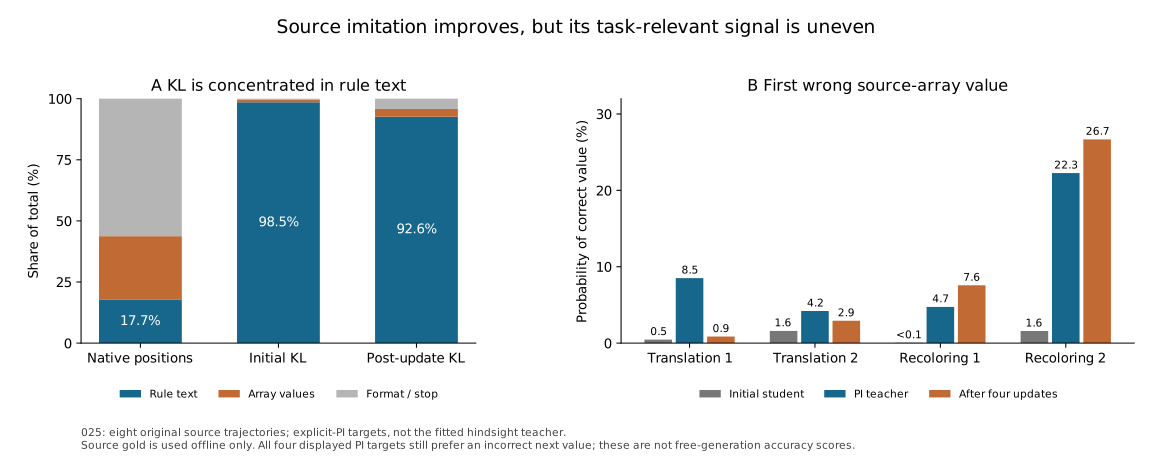
There is also a distinction between stating a rule and executing it. In at least nine of the twelve direct-context wins, the adapted response stated an appropriate transformation but violated it in the output array. One denoising answer said to keep the longest nonzero run, then copied the noisy input unchanged. The original source for that student was correct, so incorrect source trajectories cannot explain the entire gap.
These diagnostics narrow the next research question without pretending to settle its cause. The targets on historical prefixes may be weak at the actions we want to change; finite updates may fit consequential positions unevenly; and source-prefix imitation may not transfer to a fresh execution. Better average fitting alone is not a sufficient success criterion.
Optimizing the proposer with actual learning reward
The outer objective is not only a diagram. A subsequent run trained the lesson proposer using the measured reward of real student updates. For each source, it sampled four candidate lessons, applied matched sixteen-step updates, and evaluated the resulting students on validation tasks. Leave-one-out REINFORCE updated the proposer when candidate rewards differed; tied groups correctly produced no optimizer update.
The completed training audit verifies 32 source groups, 128 proposals and 14 actual proposer updates. This exercises the black-box route from a proposed lesson through a student update back to a proposer gradient. It is not evidence that the trained proposer teaches better on fresh sources: a complete held-out utility comparison was not recovered. The report preserves that distinction, the numerical likelihood limitation and the incomplete experiments rather than filling in the missing result.
The key lesson for the research design is to keep the reward attached to the behavior we ultimately want. A proposer that writes convincing advice, a teacher that predicts its policy accurately, and a student that follows the advice while reading it can all look successful before durable learning has been established.
How this connects to existing work
On-policy self-distillation supplies the aligned teacher–student distribution interface. PAST already uses completed trajectories to build a privileged teacher, and LOPD makes privileged context learnable. Meta Pseudo Labels is a direct precedent for valuing a teacher through the performance of the student it trains. Bidirectional-to-causal distillation also predates this project, and recent self-distillation diagnostics reinforce the need to evaluate the student rather than infer success from teacher strength.
The design investigated here combines source-derived teaching candidates, post-update cross-task selection and amortized policy assignment from raw experience. Its value must be established as a whole, not claimed from the novelty of one ingredient or the success of one intermediate loss.
The research direction
The ambition is a learning system that can make better use of its own completed experience: not simply store a reflection, but learn what to reinforce, what to correct and when not to update. Expensive outer training would teach a compact inner operation to assign useful policy targets directly.
The implementation makes that research question executable, and the study makes its bottlenecks measurable. It demonstrates source-derived contextual utility, a case of parameter transfer, and generalizing hindsight-distribution fitting. It does not yet establish reliable downstream improvement from the full learned procedure. The strongest next experiment should make the teaching signal useful first, then ask whether the learned hindsight teacher preserves that value—not optimize an increasingly elaborate system around an unhelpful target.
The technical report develops the method, controls, paired results, diagnostics and earlier evidence. The repository provides the implementation, a CPU quickstart, deterministic task generation, distributable result records and offline analysis. Rebuilding the historical evidence is separate from running a new GPU experiment.